
Software · Bench Test
Need transcription today? Use Whisper large-v3-turbo — via whisper.cpp (free, terminal) or MacWhisper (free tier, Pro €64 once) if you want an app. On our own audiobook clips it cost nothing and made ~2 errors per 100 English words at ~55× real-time on one Mac. NVIDIA’s Nemotron 3.5 Transcribe was the most accurate engine we measured — but today there is no Nemotron app to buy: web demo, $2/hour API, or a data-centre GPU.
NVIDIA released Nemotron 3.5 Transcribe on 28 October 2026: a free, open-weights speech model that claims 40 languages, speaker labels, and better accuracy than OpenAI’s Whisper — the model that quietly powers most of the free transcription apps on your Mac. The claim is specific and falsifiable, which means it can be measured. So we did: two public-domain audiobook chapters (one English, one French), the exact printed text as ground truth, every engine on the same audio, Word Error Rate computed by our own script. Whisper ran locally on our hardware; Nemotron ran through NVIDIA’s own free web demo, because that is the only way a normal person can run it today. That asymmetry is the whole story of this test.
How we tested
Two clips, both uncontested public domain, both read by professional-grade narrators with no noise, no overlap, no accent — the easiest case any transcriber will ever see:
| English | Alice’s Adventures in Wonderland, chapter 1 (LibriVox, read by Christy McQuillan, 2005). 10 min 40 s, 2,189 words in scope. Reference text: the exact chapter from Project Gutenberg ebook #11. |
| French | Le Tour du Monde en Quatre-Vingts Jours, chapter 1 (recording by Damien Genevois, via litterature audio / archive.org, CC BY-NC-SA). 6 min 39 s, 1,117-word span. Reference text: the chapter from Wikisource. Note: this recording stops mid-sentence at “il faut convenir que…” — every engine faced the same truncated tape, so the comparison stays fair. |
Engines: whisper.cpp (Homebrew, Metal build, default beam-5 search) with large-v3-turbo and with full large-v3; mlx-whisper (Apple’s MLX port, large-v3-turbo); and NVIDIA Nemotron 3.5 Transcribe via NVIDIA’s official Hugging Face Space (podcast mode). Machine: an Apple M5 Ultra with 256 GB RAM, macOS 27.2 — deliberately a monster of a Mac; speed numbers scale down with the box. Scoring: case-insensitive WER with punctuation stripped and accents folded, computed against the printed text between two anchor phrases, so the LibriVox licence jingle and the missing tail of the French tape don’t distort the number. Every transcript, the reference texts and the scoring script are in our bench folder; corrections welcome via the contact page.
Results
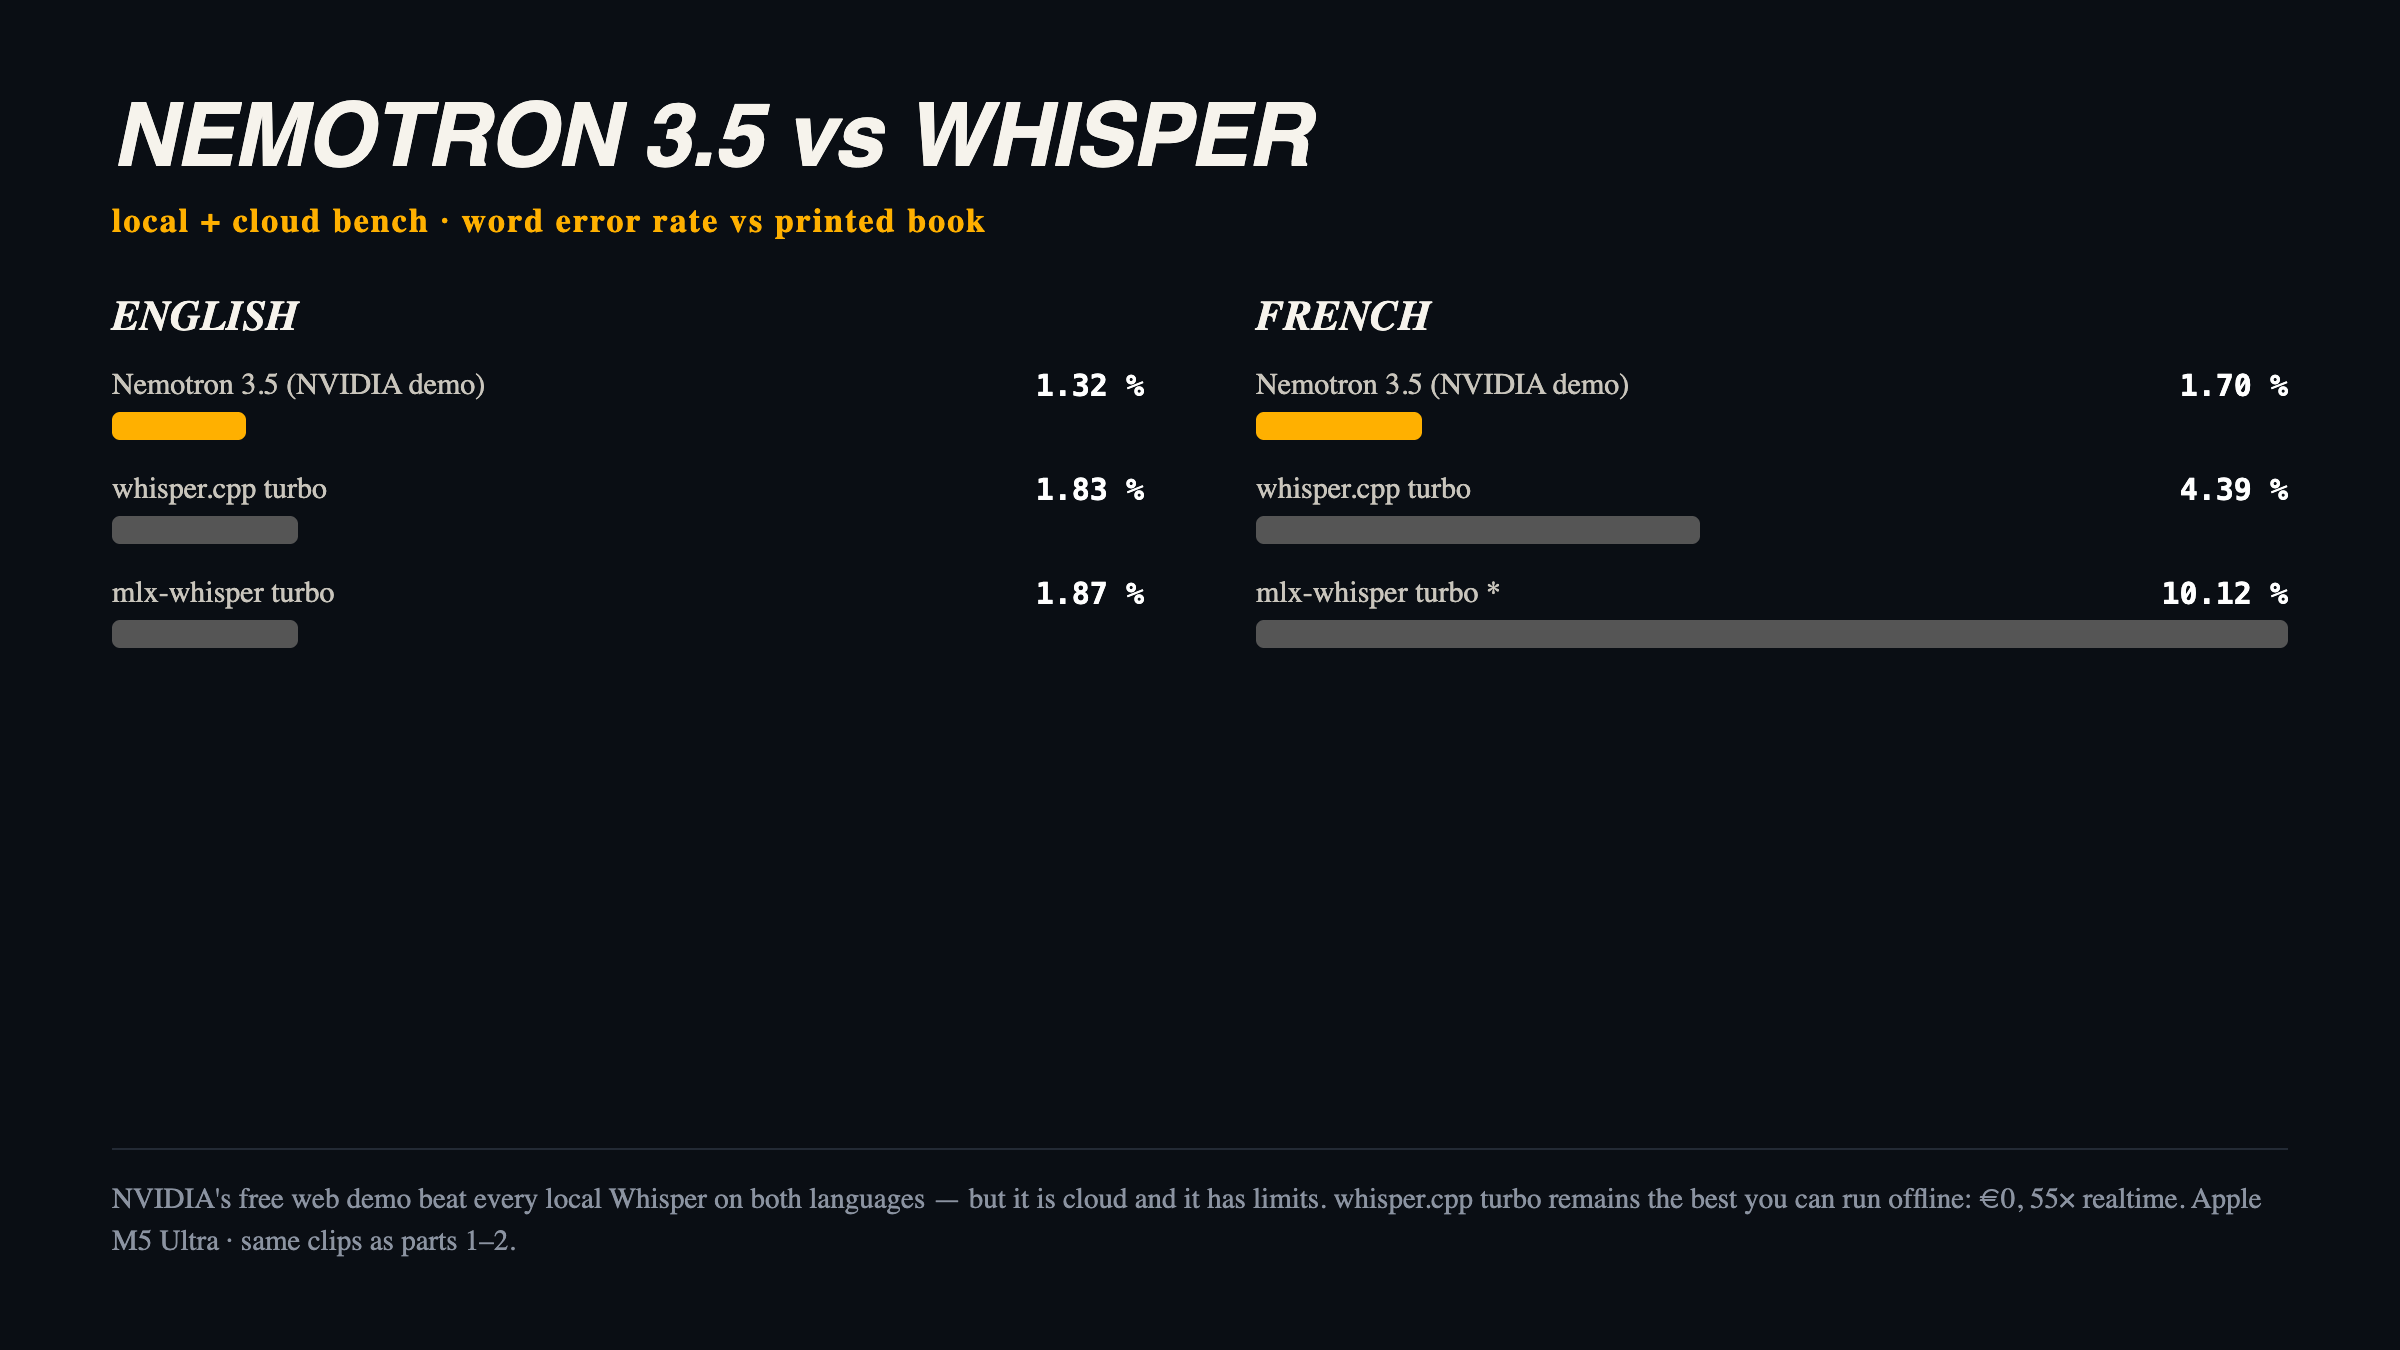
| Nemotron 3.5 Transcribe — NVIDIA web demo (cloud) | EN 1.32 % · FR 1.70 % | 10-min clip in 13 s end-to-end (download 3.9 s, model 6.9 s); FR in 11 s. Speaker labels included. Cost: free demo, or ~$2.00/hour via DeepInfra. |
| whisper.cpp large-v3-turbo — local, beam-5 | EN 1.83 % · FR 4.39 % | 10-min clip in 11.5 s (≈55× real-time); FR 7.5 s. €0. This is the number that should end most subscription arguments. |
| mlx-whisper large-v3-turbo — local (Apple MLX) | EN 1.87 % · FR 10.12 %* | 13.2 s / 4.9 s. €0. *The package ships greedy decoding — its beam search literally raises “not yet implemented” — and on French it silently dropped a 72-word paragraph. |
| whisper.cpp large-v3 (full) — local, beam-5 | EN 10.92 %* · FR 6.36 % | 40.5 s / 24.4 s. €0. *It fell into a repetition loop in the last third of the English chapter — the phrase “it was a good thing to do…” printed fourteen times — and skipped ~50 words around it. |
So the headline claim holds on our audio: Nemotron beat every Whisper configuration, in both languages, and its French result (1.70 %) is more than double as accurate as the best local Whisper run (4.39 %). NVIDIA’s hosted pipeline is also fast — 13 seconds for ten minutes of audio including the download — although a local turbo model on a modern Mac (11.5 s, no upload) is close enough that the difference is convenience, not physics. One honesty note: Nemotron’s demo transcribes in spoken style by default — our French reference counted “mille huit cent soixante-douze” against the printed “1872” as errors, which are part of its 19 total edits. The demo exposes the style as an instruction; Whisper simply prints digits.
The real finding: your transcription tool is not the model, it is the decoder
Full-size large-v3 is supposed to be OpenAI’s most accurate Whisper. On our bench it looped fourteen times on one sentence and lost a page of Alice — because Whisper-family decoding (beam search conditioned on previous text) is a known runaway loop generator on long clean audio, and the turbo distillation exists partly to fix exactly this. Same weights, different package, different disaster: the MLX port’s greedy decoder deleted an entire 72-word paragraph of Jules Verne that whisper.cpp’s beam search got right. Nobody in the app stores tells you this. When a “Whisper app” transcript skips a paragraph, the model is rarely the culprit — it is the decoding options nobody exposes. If an app gives you “beam size”, set it above 1; if it doesn’t, assume greedy and spot-check long files.
What Nemotron actually brings besides accuracy
It is not a transcription model in Whisper’s sense but a speech LLM (~4.3B active parameters, paper: NVIDIA, 28 October 2026): you tell it in plain language what transcript you want — verbatim or cleaned up, numbers as digits or words, a list of hard names and terms to respect — and it adds speaker-attributed word timestamps for up to 8 speakers (13 languages) and speech translation. NVIDIA’s own numbers: 4.71 % average WER on nine public English test sets (Whisper large-v3: 6.66 %), and the independent Artificial Analysis index puts it at 3.4 % versus 4.1 % for large-v3 via fal.ai. Limits, from the same sources: recordings up to one hour, no live/streaming mode, features are uneven across the 40 languages (Dutch transcribes but doesn’t diarize), and named-entity handling still misses.
And the catch nobody can install around: NVIDIA’s reference serving target is an H100 (80 GB); its NVFP4 checkpoint claims 2,238 seconds of audio per second on an RTX PRO 6000 Blackwell, with a quantised build aimed at an RTX 5090 — a €2,000-plus GPU, still not your laptop. The weights are genuinely free for commercial use (OpenMDW-1.1, MIT-style), and DeepInfra serves them at ~$2 per 1,000 minutes. But as of today, no consumer app we can find ships Nemotron. It is a model looking for products.
The market, in euros
| whisper.cpp / mlx-whisper / openai-whisper | €0, MIT/Apache. Your GPU does the work; on the M5 Ultra 1,000 minutes of audio cost us ~10 minutes of compute and a few cents of electricity (rough estimate, not metered). |
| MacWhisper (macOS/iOS) | Free tier; Pro €64 once, lifetime updates (checked 30 Oct–4 Nov 2026). Whisper inside, diarisation, batch export, dictation. In 3-year maths it is the cheapest paid app here by a factor of four. |
| TurboScribe (web) | Unlimited $20/month, or $10/month billed yearly; 98+ languages, 10-hour files (turboscribe.ai pricing, checked Oct–Nov 2026). It runs Whisper-class and other models behind the API without publishing which — fine value for volume, zero transparency on which engine your file met. |
| Superwhisper (dictation-first) | $8.49/month, or $249.99 lifetime — three times MacWhisper’s whole price for a different job (dictating into apps). |
| Wispr Flow (cloud dictation) | $15/month, $12 billed yearly, 2,000 free words/week — it types into every app, on four platforms, but your audio lives on someone’s server. |
| Raw APIs, per 1,000 minutes | Groq Whisper large-v3-Turbo $0.67 · fal.ai Whisper large-v3 $1.15 · DeepInfra Nemotron $2.00 · OpenAI whisper-1 $6.00 (Artificial Analysis pricing table + Groq docs, Nov 2026). |
Should you switch from Whisper?
For what we can buy and run today: no, because there is nothing to switch to — and that is the answer to the question every recap of the NVIDIA launch skipped. Nemotron 3.5 Transcribe is measurably the best speech-to-text we have ever run on this desk, and it loses anyway, because transcription is a product, not a benchmark. Use whisper.cpp-turbo or MacWhisper: free-or-€64, offline (your interviews never leave the house), and good enough to be boring. If your work is French, German or Dutch interviews with several speakers talking over each other, the local Whisper gap is real — our French numbers were 2.6× worse than the cloud — and paying $2 an hour to DeepInfra, or waiting for the first Nemotron-powered app, is rational. If your job is live meeting captions, neither model helps: Nemotron explicitly has no streaming mode, and that niche stays Whisper-streaming and commercial territory.
On “should I switch to Nemotron?”: wait. Put it on a watch-list and re-test the moment it appears inside an app you would actually open — MacWhisper’s developer ships new engines fast, and the first Nemotron desktop build is the story to watch. On “should I still pay a transcription subscription?” — no. That €64 once, or the free terminal build, is the measured answer.
Method note: own measurements of 8 November 2026 on an Apple M5 Ultra, 256 GB, macOS 27.2 — whisper.cpp (Homebrew) with ggml large-v3-turbo / large-v3, mlx-whisper (pip) with mlx-community/whisper-large-v3-turbo, NVIDIA Nemotron 3.5 Transcribe via NVIDIA’s official Hugging Face Space (their pipeline, their GPU, free tier). Audio: LibriVox (Alice in Wonderland, public domain) and Damien Genevois/litterature audio via archive.org (CC BY-NC-SA). Ground truth: Project Gutenberg #11 and fr.wikisource.org. WER: our script — lower-cased, punctuation stripped, accents folded, apostrophes split, aligned between anchor phrases; both clips and all transcripts published in our bench. Published figures quoted as such: NVIDIA research page + technical report (28 Oct 2026), Artificial Analysis speech-to-text index (Nov 2026), turboscribe.ai / macwhisper.com / superwhisper.com / wisprflow.ai / console.groq.com pricing pages checked Oct–Nov 2026. Nemotron was not run locally (no H100-class hardware here); its numbers are from NVIDIA’s own hosted demo. No affiliate links in this article.