
Review · speech-to-text bench, part 3 — measured Nov 8, 2026
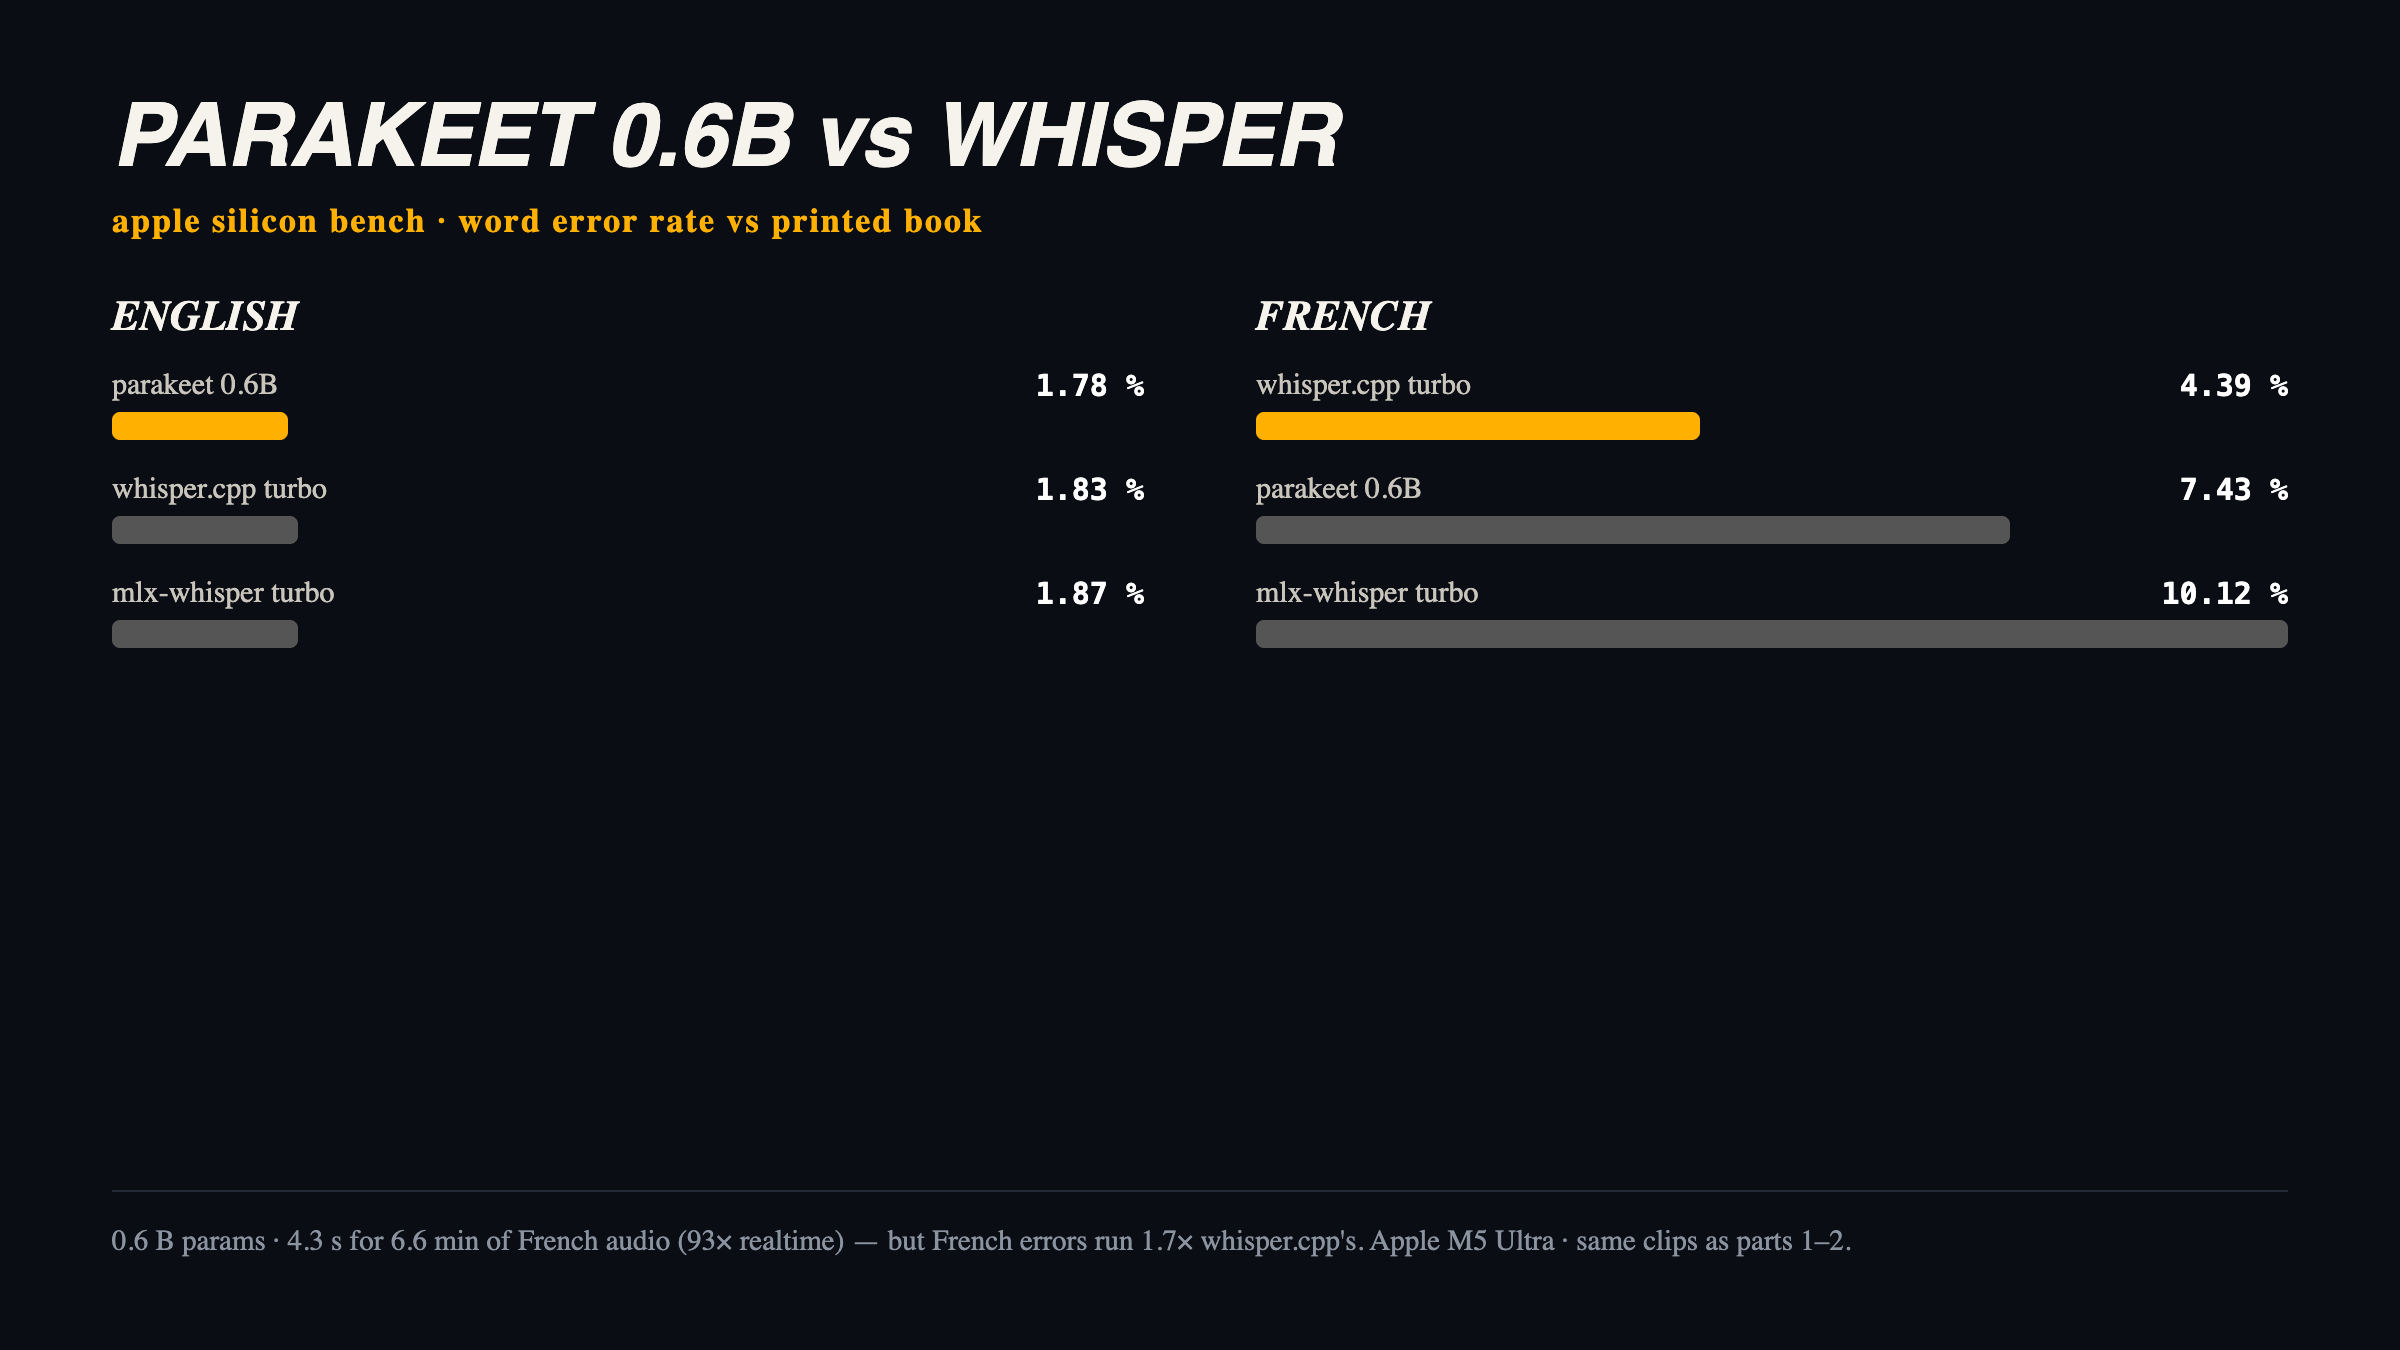
Run parakeet-tdt-0.6b-v3 through parakeet-mlx if you need fast local English — it just beat Whisper’s own turbo model. For French, it is honest but 1.7× more wrong than whisper.cpp turbo. Situational.
NVIDIA’s Parakeet-TDT 0.6B packs 25 languages into a model one third the size of Whisper large-v3-turbo, and parakeet-mlx runs it on Apple Silicon’s Metal. On our bench it transcribed six minutes of French in 4.3 seconds — 93× realtime. Accuracy was a different story, and the kind of mistakes it makes turned out to be the most interesting result of the series so far.
Model: mlx-community/parakeet-tdt-0.6b-v3 (0.6 B params, 2.3 GB fp32) Software: parakeet-mlx 0.7.0 (pip, needs Python ≥ 3.10), MLX, greedy decoding Hardware: Apple M5 Ultra, Metal — same machine as parts 1 and 2 Audio: identical clips — Alice in Wonderland ch. 1 (EN, 640 s) · Jules Verne ch. 1 (FR, 399 s), LibriVox Scoring: word-error rate against the printed text, same anchored Levenshtein method as part 1
The numbers
| Engine (local) | English WER | French WER | Time EN | Time FR |
|---|---|---|---|---|
| parakeet-tdt-0.6b-v3 | 1.78 % | 7.43 % | 4.9 s | 4.3 s |
| whisper.cpp + large-v3-turbo | 1.83 % | 4.39 % | 11.5 s | 7.5 s |
| mlx-whisper + large-v3-turbo | 1.87 % | 10.12 % | 13.2 s | 4.9 s* |
| whisper.cpp + large-v3 (full) | 10.92 % | 6.36 % | 40.5 s | 24.4 s |
*The mlx-whisper French run looks fast partly because it silently dropped a 72-word passage — deleting words is the cheapest optimization there is. That failure mode is what [our part 2 write-up](/mlx-whisper-french-silent-omission-bench/) is about.
In English, parakeet is the new local leader: the lowest word-error rate we have measured on a local model, beating both turbo runs by a hair while being 2.3× faster than whisper.cpp. In French it lands in the middle — clearly better than mlx-whisper’s 10.12 %, clearly worse than whisper.cpp’s 4.39 %.
The finding: it fails differently
Parts 1 and 2 were about Whisper’s global failures: whisper.cpp large-v3 looped the same clause 14 times over, mlx-whisper swallowed 72 words without a sound. We diffed every word of the parakeet French transcript against the printed page to hunt for the same pattern — and there were no loops and no dropped passages at all. It emitted 1,113 words against the reference’s 1,117 and kept the plot intact start to finish.
What it does instead is fail locally, at the word level, in ways you can actually see:
- Grammar endings eroded: « ses paroles s’étaient trouvées souvent » → « ses paroles s’était trouvé souvent »; « un collège d’avocats » → « un collège d’avocat »; « ses gains n’entraient jamais » → « ses gains n’entrait jamais ». Dozens of these — it hears the French but writes the wrong inflection.
- One invented date: the novel opens « En l’année 1872 » — parakeet wrote 1861. Whisper got it right. This cost us the shared anchor and is exactly the kind of error that survives into a clean-looking transcript.
- One moment of English leakage: « ce » came out as « the » once, inside an otherwise French sentence.
- Rare words re-split: « Londonner » (to London) became « l’onde d’honneur »; « docks » became « dogs ».
For most real uses that ranking matters more than the headline WER. A dropped passage is silent — you only find it by diffing against the audio. « avait » instead of « avaient » you fix in editing, or you notice because the sentence reads wrong. Parakeet trades a worse error count for errors that are visible and local.
What it costs you
Two friction points, both cheap: parakeet-mlx needs Python ≥ 3.10 (our bench venv is 3.12 via uv), and the fp32 weights are 2.3 GB on disk — bigger on disk than Whisper’s 1.6 GB turbo pack despite fewer parameters, though it runs at half the parameter count once loaded. Model is 25-language ASR only: no translation, unlike Whisper.
Verdict
If your work is English — meetings, dictation, podcasts — parakeet-tdt-0.6b-v3 is now the best local model we have measured: faster and more accurate than Whisper turbo on the same hardware, with no loops and no silent drops. If your work is French, keep whisper.cpp + large-v3-turbo for accuracy, or run parakeet knowingly: it will not lose your paragraphs, but it will misspell the endings and it got a date wrong in our run.
Same audio, same printed-text ground truth, same scoring anchors as parts 1 and 2 — with one disclosed deviation: parakeet’s French transcript opens with « En l’année 1861 », so we anchored the alignment on « en l’année » instead of the year. The full diff method is documented on the [benchmarks hub](/benchmarks/).